GitHub Copilot Fusion updates: more availability, benchmarks, and models
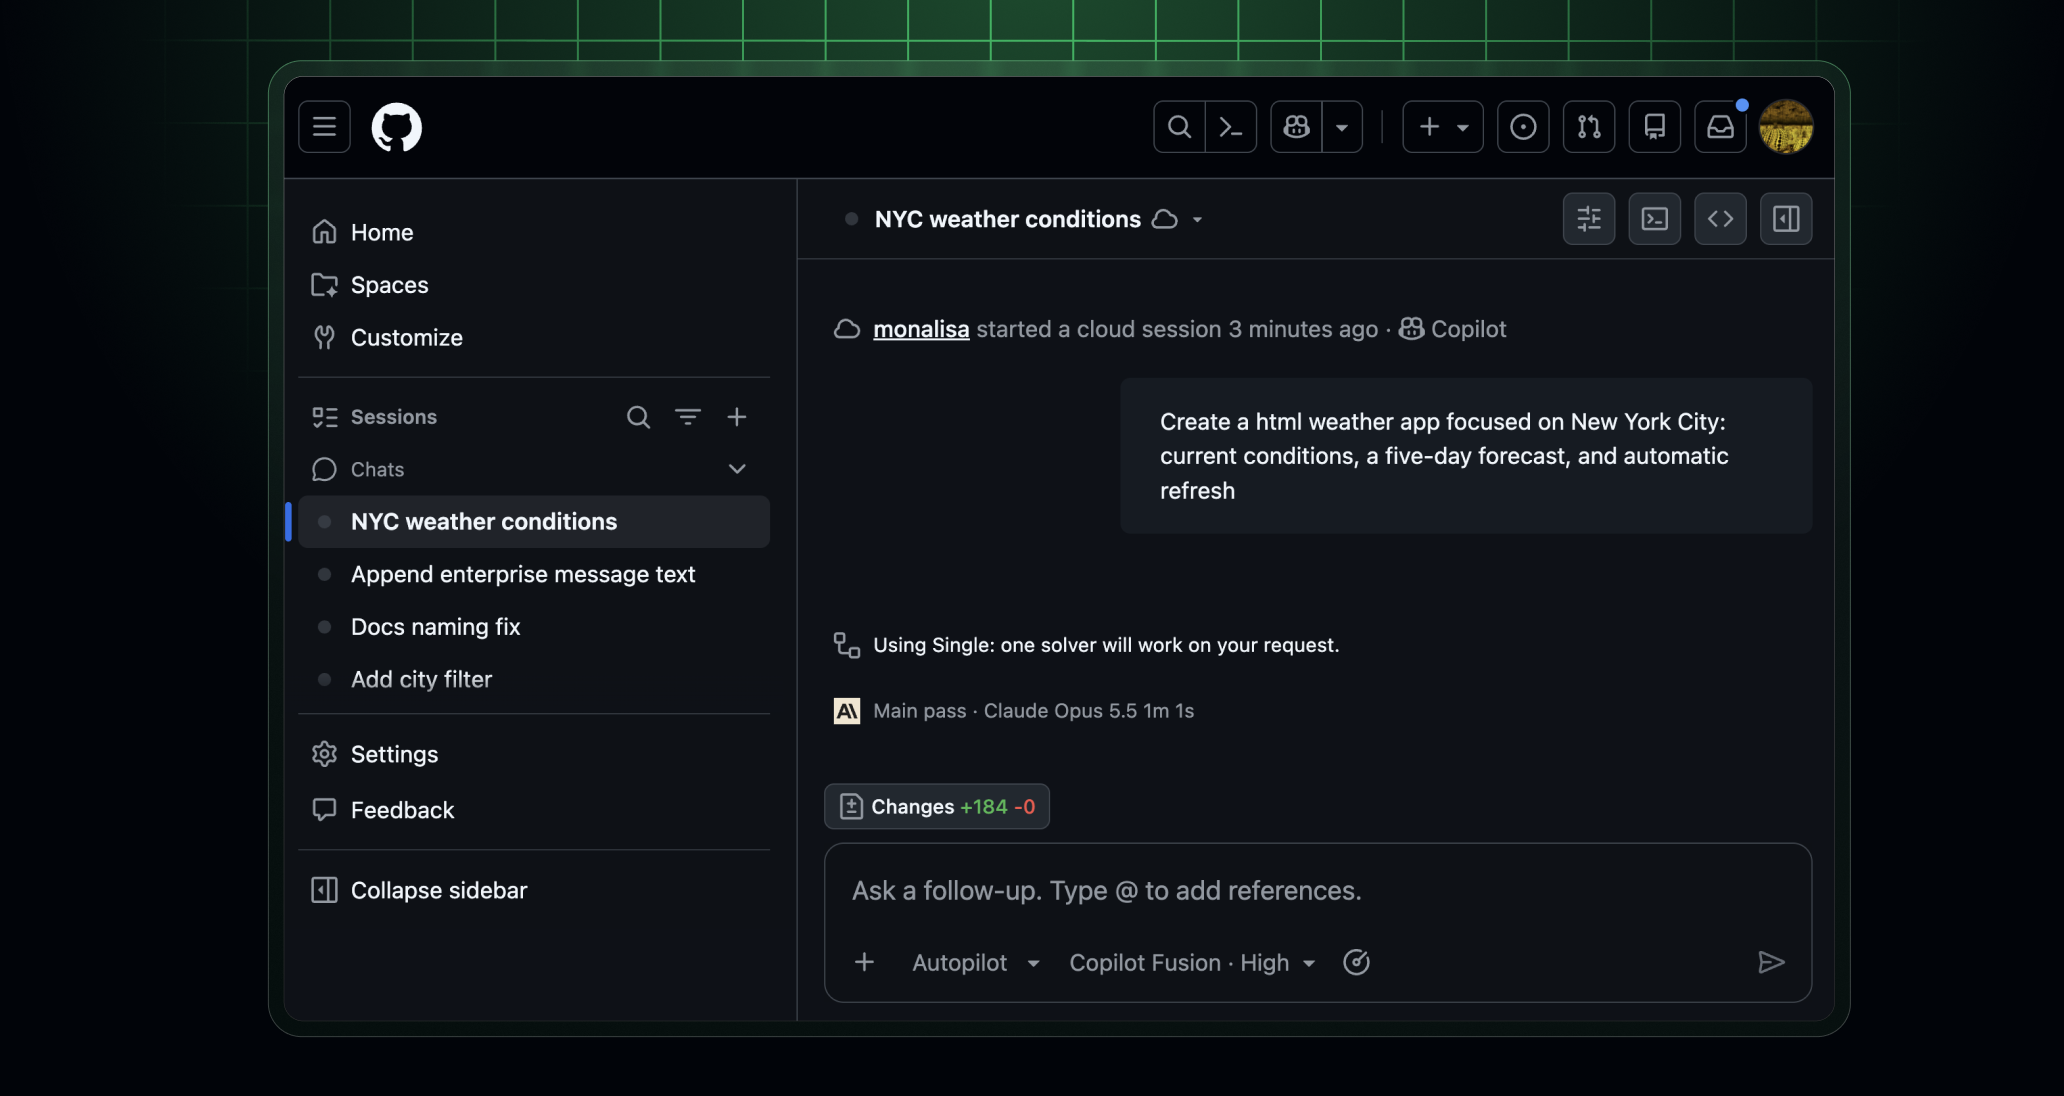
Today, we’re expanding GitHub Copilot Fusion with new models, available on more Copilot surfaces, and results on two public Terminal-Bench leaderboards, giving you more ways to use Fusion and compare its performance.
GitHub Copilot Fusion joins public Terminal-Bench 4.1 leaderboard
Copilot Fusion is now listed on Terminal-Bench 4.1 public leaderboards hosted by Stanford, Harbor, and the Laude Institute: Terminal-Bench 4.1 measures how well AI agents complete hard, realistic tasks in a terminal.
On Terminal-Bench 4.1, Copilot Fusion Max achieved a 71.2% resolution rate, 5.4 percentage points ahead of leading frontier models Opus 5.5 and Fable 5.2, while costing 88% less than Fable 5.2 and 57% less than Opus 5.5.
Independent leaderboards let you compare Copilot with other agents on the same tasks, using the same evaluation rules.
Copilot Fusion is now available on web, mobile, and Visual Studio
Copilot Fusion is coming to more places you use Copilot. With this release, you can select Copilot Fusion on the latest versions of github.com, Visual Studio, and GitHub Mobile beta apps for iOS and Android. Support in the production GitHub Mobile apps is coming shortly.
Select Copilot Fusion in the model picker and let it choose and coordinate models for each task. You set the effort level and Copilot handles the rest.
More models added
With this release we are adding:
- Claude Sonnet 5.5 to Copilot Fusion Max
- GPT-6.1 Terra to Copilot Fusion High
- MAI-Code-2 to Copilot Fusion Standard
Learn more
Read more about Copilot Fusion.