ReviewBench: An open benchmark for AI code review
We’re launching ReviewBench, a benchmark for code review agents built on representative GitHub pull requests, multi-source ground truth, calibrated evaluation, and production-aligned metrics.
We’re launching ReviewBench, a benchmark for code review agents built on representative GitHub pull requests, multi-source ground truth, calibrated evaluation, and production-aligned metrics.
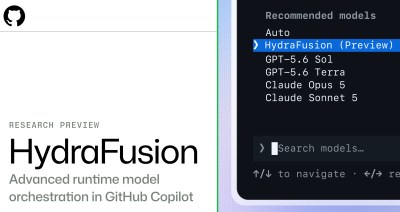
In controlled offline evaluations, HydraFusion’s selective coding workflows matched or exceeded the evaluated Opus 5 baseline while reducing estimated workflow cost. Now available as a research preview in GitHub Copilot.
Explore how the GitHub Copilot agentic harness delivers strong results across multiple benchmarks and leading token efficiency, while maintaining flexibility to choose among more than 20 models.

Build what’s next on GitHub, the place for anyone from anywhere to build anything.

Join us October 28-29 in San Francisco or online for GitHub Universe, our flagship developer event uniting people, agents, and the world’s code.

